Show HN: Nari Qwen3-TTS and Qwen3-ASR – High accuracy, low latency and cost
Nari Labs claims top Coval voice AI benchmark rankings with low-latency, low-cost Qwen3-ASR and Qwen3-TTS inference endpoints.
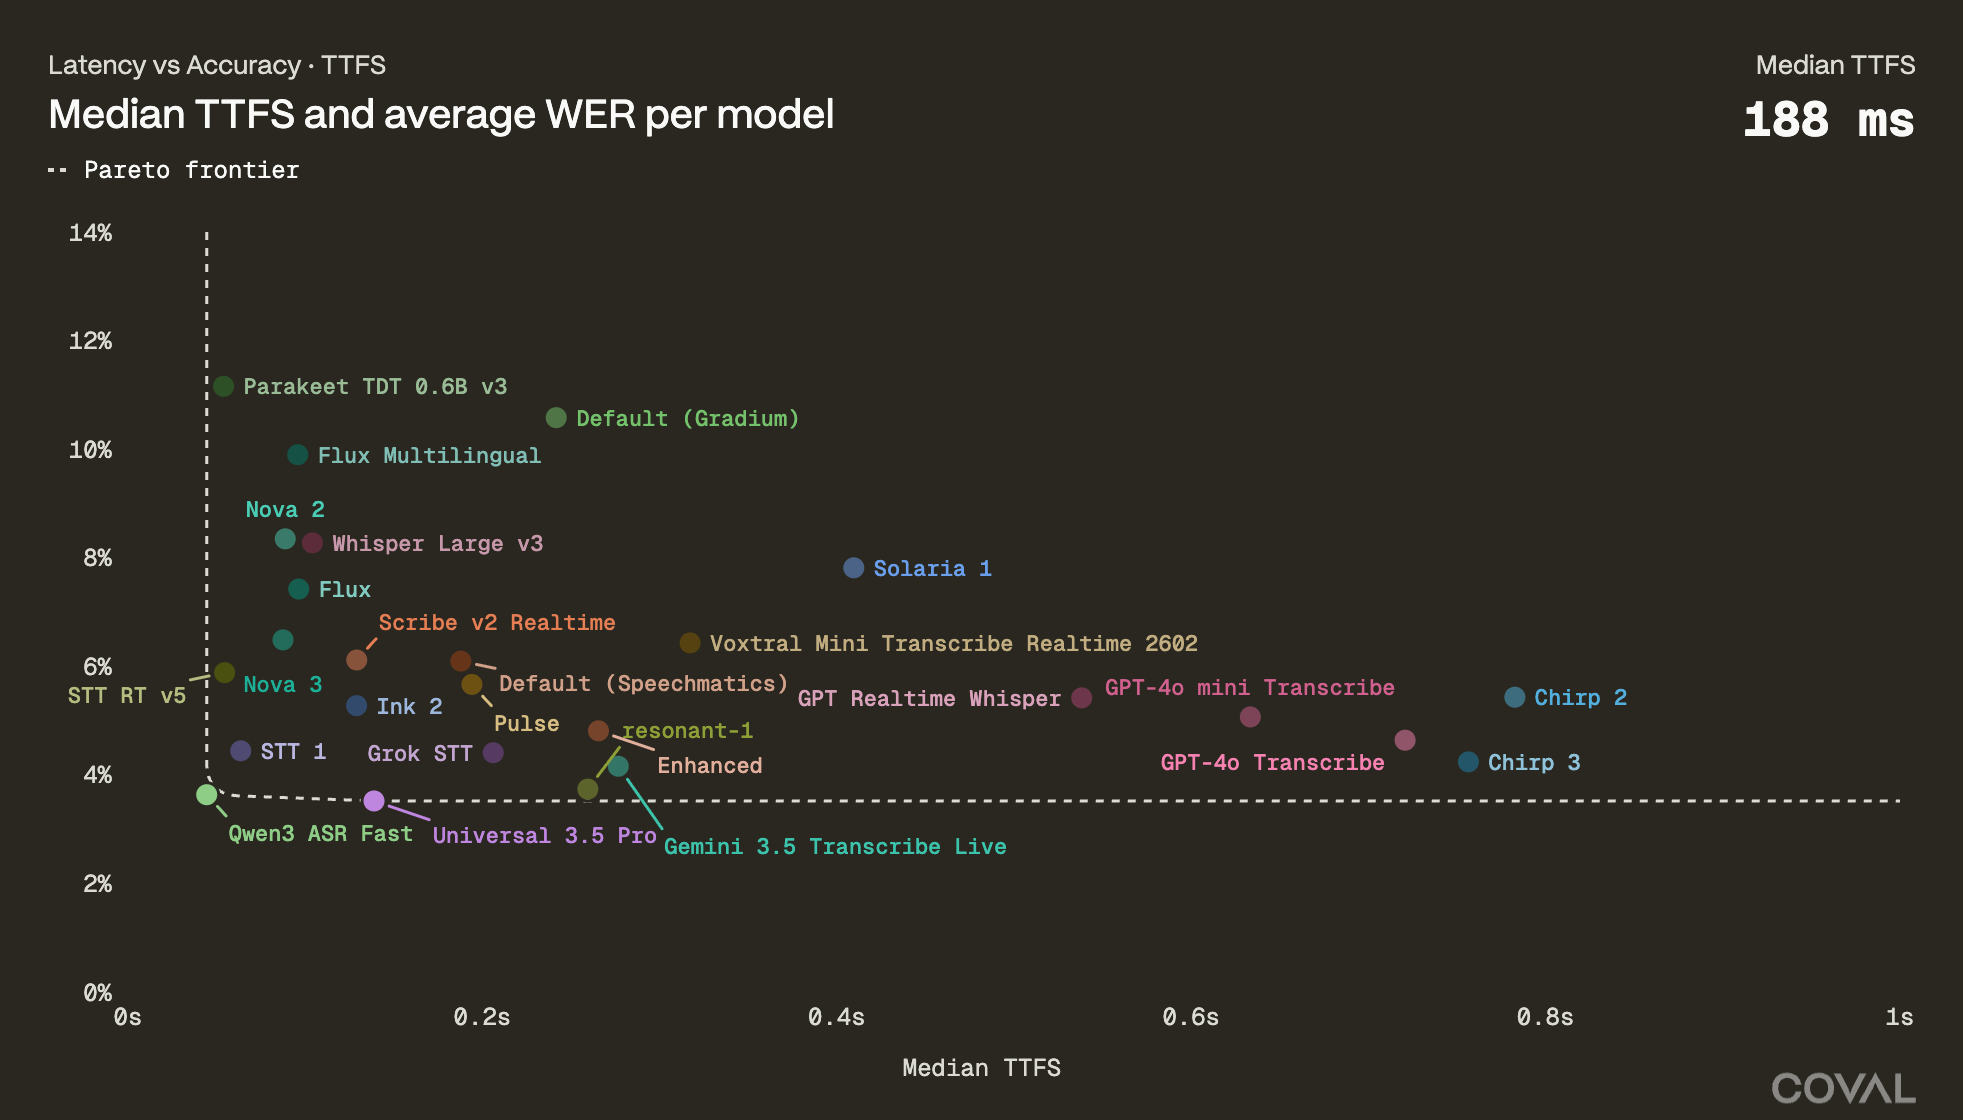
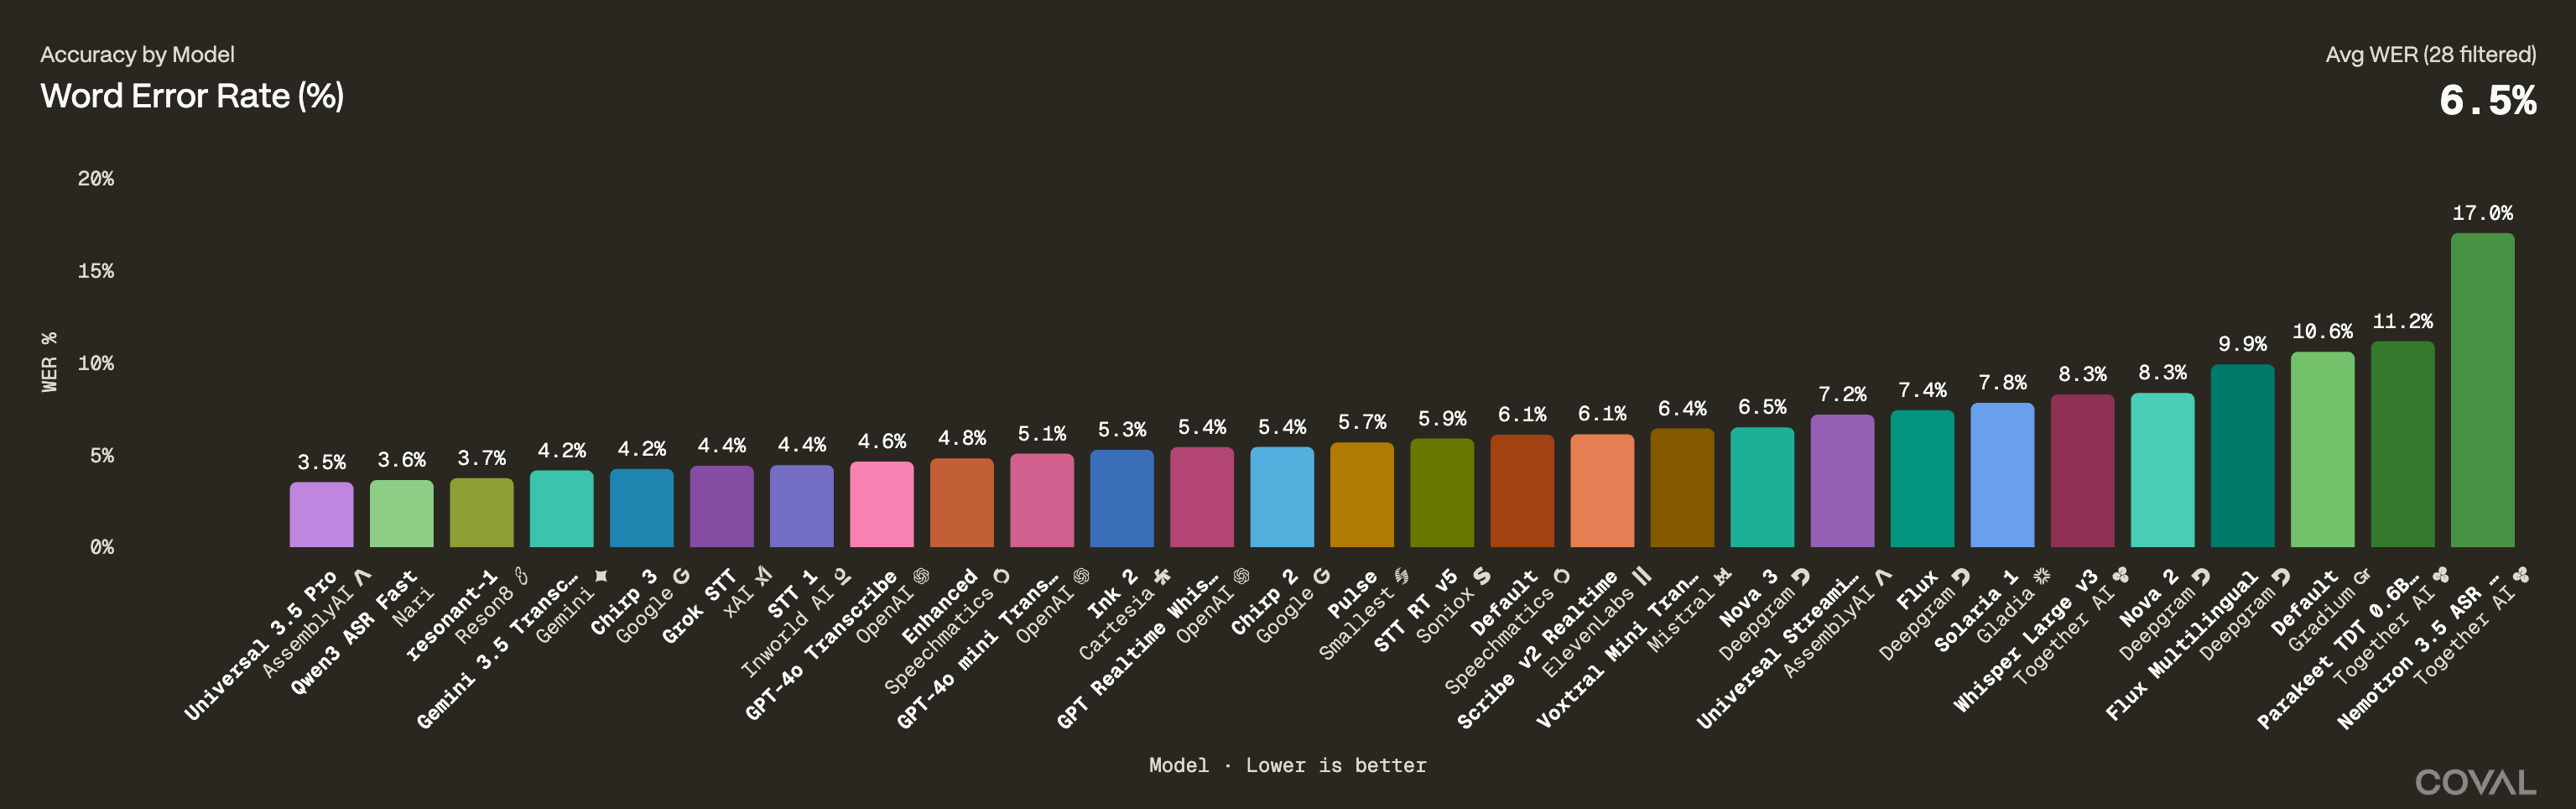
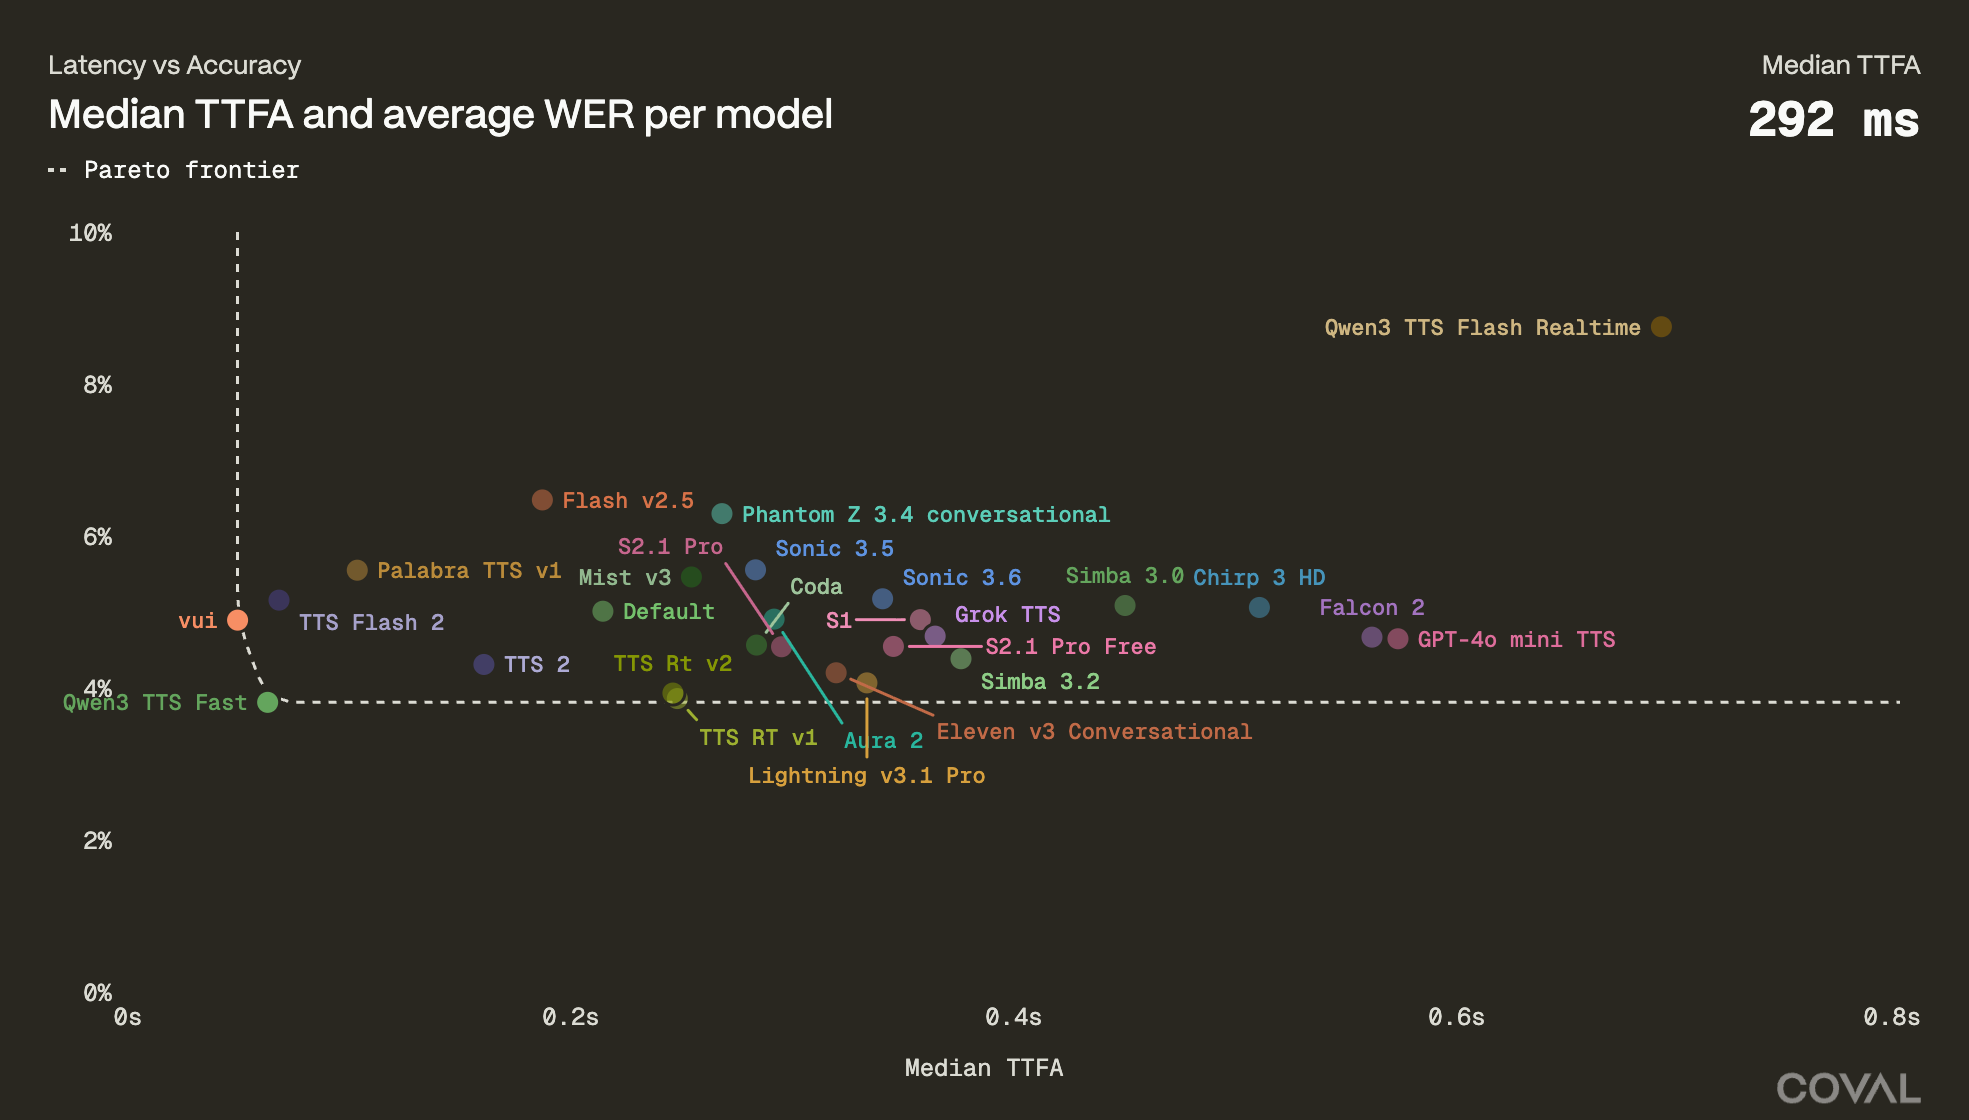
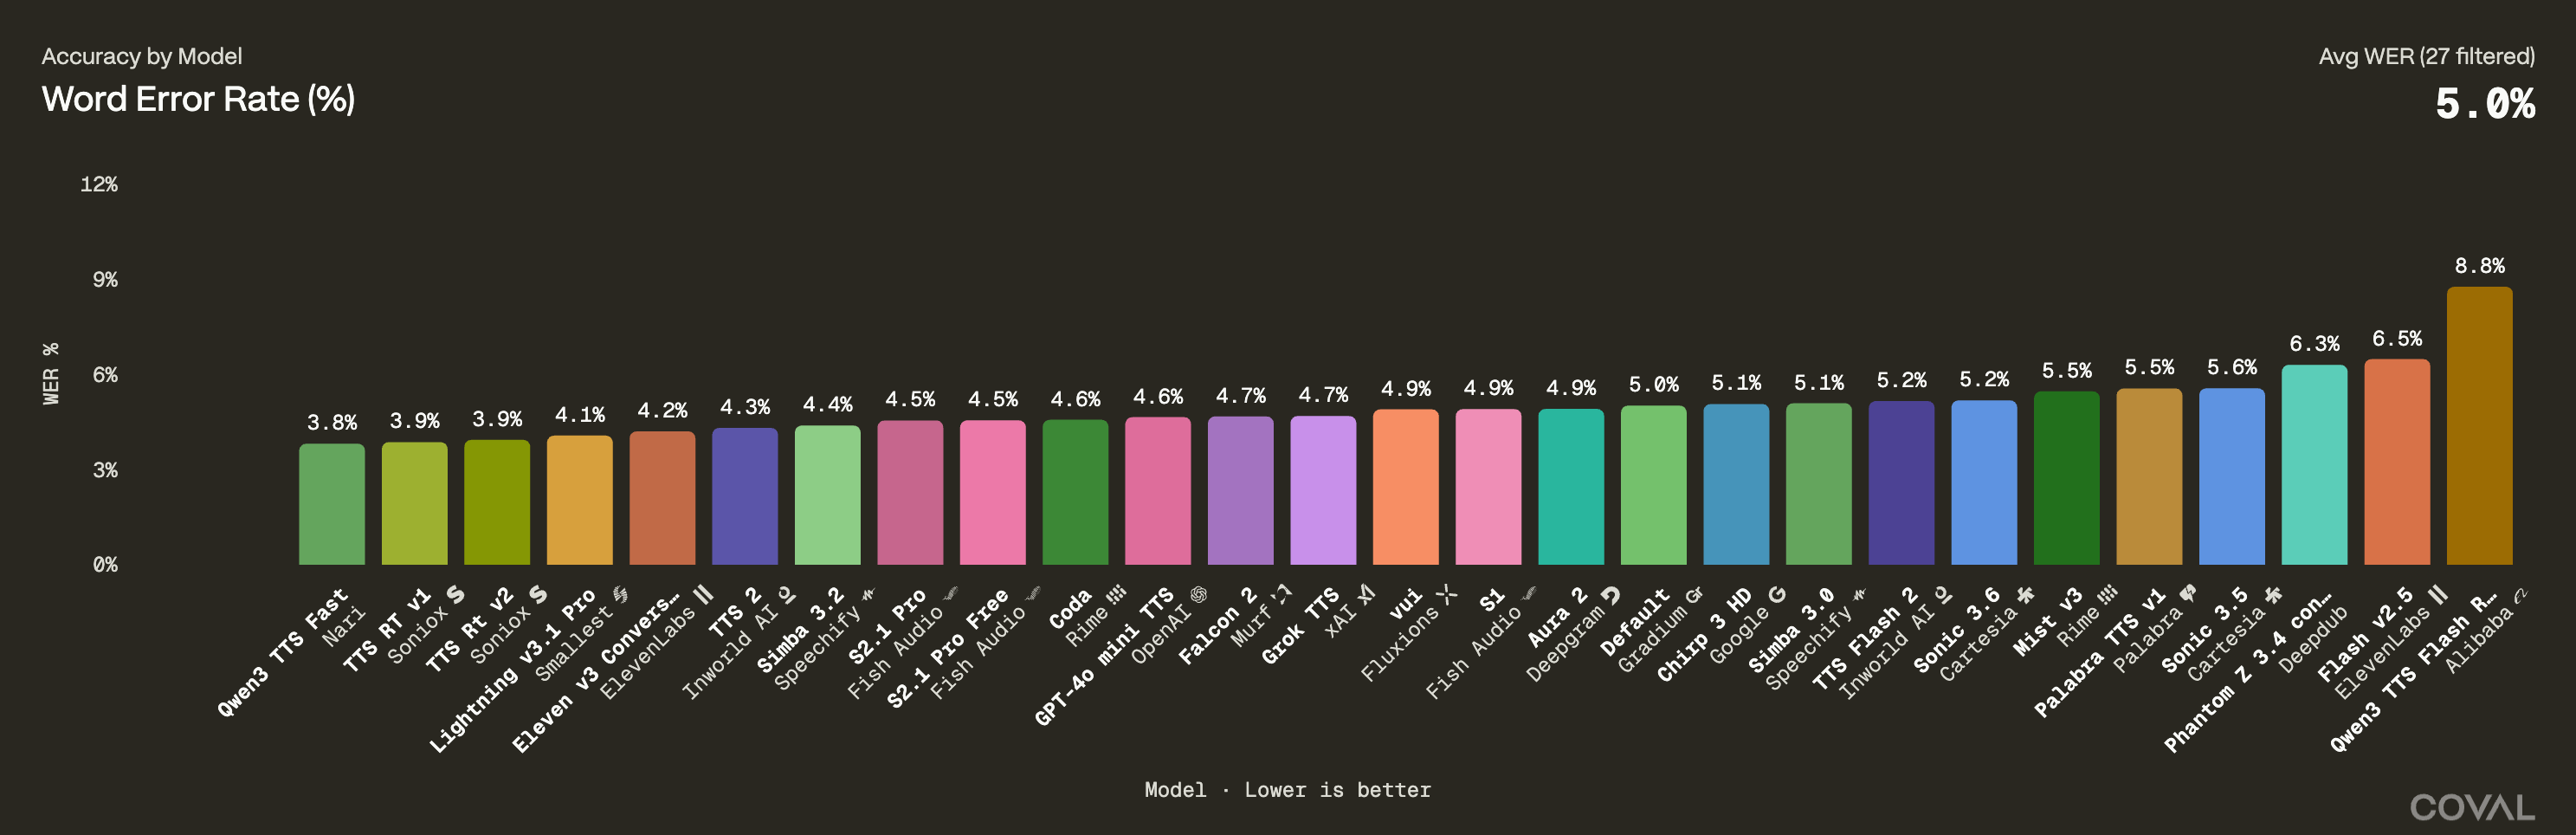
Nari Labs says its Qwen3-ASR Fast endpoint ranks #1 in Coval's time-to-final-segment latency (p50 44 ms) with 3.6% WER at $0.12/hour, behind only AssemblyAI Universal 3.5 Pro on accuracy. Its Qwen3-TTS Fast ranks #2 in time-to-first-audio (p50 63 ms) and #1 in WER at 3.8%, priced at $10 per 1M characters. The company reports beating the official Qwen3 TTS Flash Realtime endpoint (8.8% WER, 692 ms median TTFA) and Baseten's dedicated endpoint (6.0% WER, 101 ms). Public beta APIs are moving to paid general availability with $20 in credits for existing accounts.
- Qwen3-ASR Fast: p50 44 ms TTFS, 3.6% WER, $0.12/hour, ranked #1 latency on Coval.
- Qwen3-TTS Fast: 63 ms TTFA, 3.8% WER (best), $10 per 1M characters.
- Outperforms official Qwen3 endpoint (8.8% WER, 692 ms) and Baseten (6.0% WER, 101 ms).
- Beta APIs move to paid GA shortly, with $20 credits for existing accounts.
Full article550 words · extracted from narilabs.com · click to collapse
Research
By the Nari Labs Team · Sep 14, 2026
TL;DR
Nari Labs leads Coval’s voice AI benchmark by sitting on the quality-latency Pareto Frontier for both Text-to-Speech and Speech-to-Text. We also lead the latency-cost and quality-cost Pareto Frontier out of all publicly available models on the benchmark.
Coval is a leading provider of voice AI evaluation and benchmarks. They help speech AI agents perform better in production and publish one of the most widely cited benchmarks in the industry.
The Text-to-Speech (TTS) benchmark evaluates latency from text input to first audible chunk of audio (time-to-first-audio or TTFA) and Word Error Rate (WER). The Speech-to-Text (STT) benchmark evaluates latency from user’s finalize request to the final text output (time-to-final-segment or TTFS) and Word Error Rate (WER).
TTFA and TTFS are critical for voice agents, where latency can make a voice AI agent feel unresponsive. Low WER is an obvious key factor for model performance as well.
As of mid September 2026, Nari Labs tops both the Speech-to-Text and Text-to-Speech benchmarks. STT: #1 Latency, #2 WER. TTS: #2 Latency, #1 WER. Note that Coval’s benchmarks can fluctuate every 30 minutes*. We only include publicly available endpoints in our rankings and charts.
Speech-to-Text
Our Qwen3-ASR Fast model is ranked #1 in Time-to-Final-Segment (TTFS), at p50 of 44 ms and WER of 3.6%, placing #2 behind AssemblyAI’s Universal 3.5 Pro at 3.5%.
The pricing makes it even better. At $0.12 / hour, our Fast endpoint ties for the 2nd-lowest price among models with known public rates in Coval’s pricing directory. Universal 3.5 Pro costs 3.75× more, and Deepgram Nova 3 costs 2.4× more. Our Standard endpoint would be the cheapest at $0.06 / hour.
 Nari Labs
 Nari Labs
Text-to-Speech
Our Qwen3-TTS Fast model is ranked #2 in Time-to-First-Audio (TTFA), at p50 of 63 ms and WER of 3.8%, coming in at #1.
The only model with a lower median TTFA than ours is vui from Fluxions, at 49 ms. It is a 300M parameter model, compared to the 1.7B Qwen3-TTS that we serve.
At $10 per 1M characters, our Fast endpoint is tied for the #1 cheapest model on Coval’s pricing directory. ElevenLabs Eleven v3 Conversational costs 5x more, and Cartesia Sonic 3.6 costs 6.5x more. Our Standard endpoint would be the cheapest at $5 per 1M characters.
 Nari Labs
 Nari Labs
Interestingly, the official Qwen3 TTS Flash Realtime endpoint sits at 8.8% WER and 692 ms median TTFA. We both serve the same model.
We also surpass Baseten’s dedicated Qwen3-TTS endpoint, which records 6.0% WER and 101 ms median TTFA.
Get Started
Try both our Speech-to-Text and Text-to-Speech models for free for a limited period of time. We are moving our Public Beta APIs to a paid GA within this week and will provide $20 in credits for everyone who has created an account when the switch happens.
Need help meeting the latency and capacity requirements of your voice application? Talk to our engineers
* Benchmark values in this post are based on Coval’s 1-day view as of September 14, 2026, at 15:00 UTC. WER is pooled across datasets. Rankings exclude dedicated inference endpoints. Prices compare Nari’s published rates with known public rates in Coval’s pricing directory.
Text extracted automatically; images, tables and formatting may be missing. Original: https://narilabs.com/blog/nari-labs-leads-coval-voice-ai-benchmarks/